|
Bharat Runwal
Doing frontier-adjacent things with non-frontier amounts of compute.
I am a Research Engineer at the
MIT-IBM Computing Research Lab,
where I lead model architecture, pretraining, and mid-training
efforts for IBM's Granite Next series of models.
I received my B.Tech. in Electrical Engineering
(Power and Automation) from the
Indian Institute of Technology Delhi (IIT Delhi)
.
Email /
Google Scholar /
Twitter /
Linkedin /
Github
|
|
Research Experience
|
Research Intern
Jan 2023 – Sep 2023
MIT
Collaborators:
Yilun Du,
Prof. Josh Tenenbaum
Research Topic: Continual Generative Modeling
|
|
Visiting Research Scholar
Jan 2022 – Mar 2023
CERC-AAI Lab,
Mila – Quebec AI Institute
Collaborators:
Diganta Misra,
Irina Rish
Research Topics: Sparsity, Continual Learning
|
|
Research Intern
Jun 2021 – Oct 2021
Internet of Everything (IoE) Group
,
University of Cambridge
Collaborators:
Arunava Das,
Dr. Oktay Cetinkaya,
Prof. Özgür B. Akan
Research Topic:
Received Signal Modeling and BER Analysis for Molecular SISO Communications
Publication:
ACM NanoCom 2022
|
|
Research Intern
Oct 2020 – May 2021
Deep Data Lab,
Hasso Plattner Institute, Potsdam, Germany
Supervisor:
Prof. Gerard de Melo
Research Area: Natural Language Processing (NLP)
|
Work Experience
|
Research Engineer
Mar 2025 – Present
IBM Research
· MIT-IBM Computing Research Lab
Manager:
Rameswar Panda
Leading work on model architecture, large-scale training
optimizations, pretraining, and mid-training for IBM's
Granite Next series of models. Previously, I was part of
the core team behind the
Granite 4.0 family of models
.
|
|
Research Engineer
Mar 2024 – Aug 2024
Simbian
Spearheaded the development of the Security Accelerator,
improving threat hunting and detection in the cybersecurity domain.
|
|
AI Research Intern
Jun 2021 – Aug 2021
AlphaICs
Research Areas:
Neural Network Quantization and Graph Neural Networks (GNNs)
|
|
Junior Machine Learning Engineer
Jun 2021 – Aug 2021
Omdena
Project:
Helping People with Visual Impairment to Easily Use Buses
through Computer Vision
|
|
NLP Intern
May 2021 – Jun 2021
Zevi
Worked on a vernacular search engine for e-commerce
applications, including price-tag detection from queries,
autocomplete, and spell checking.
|
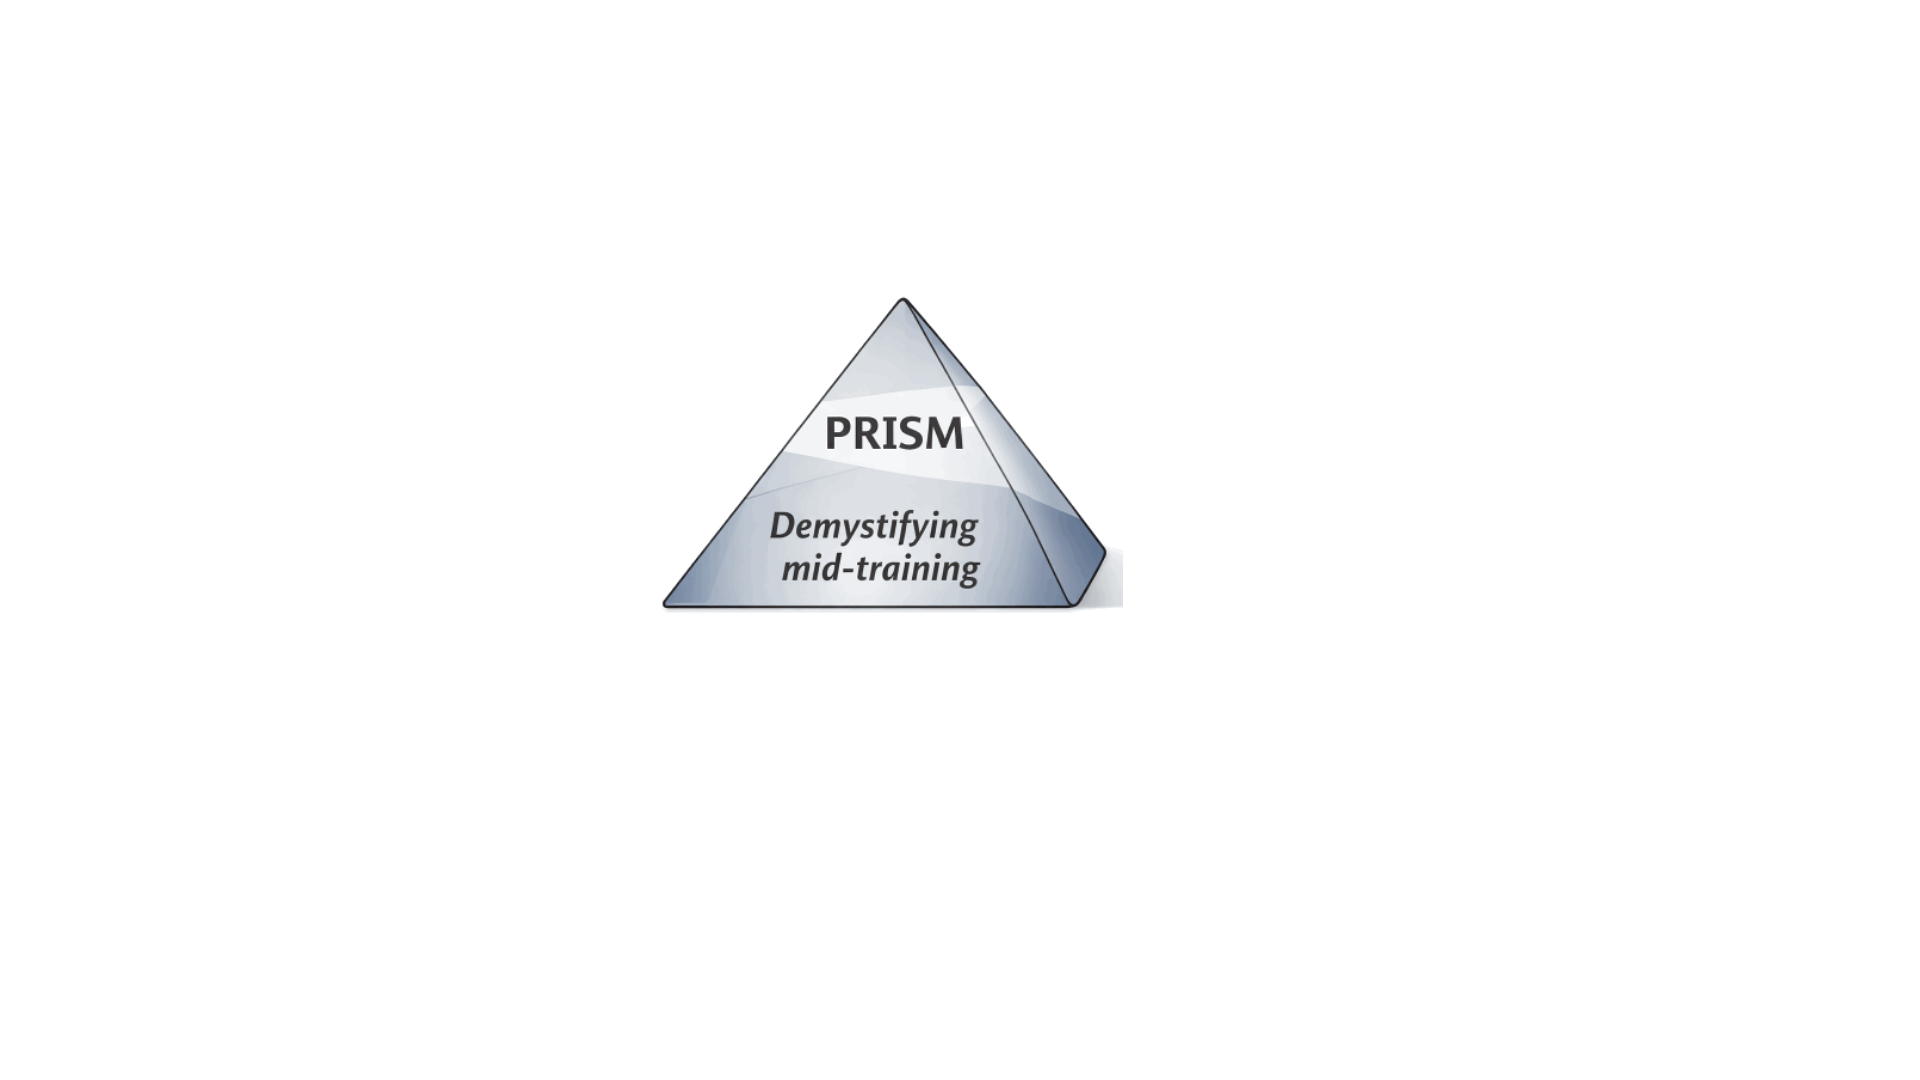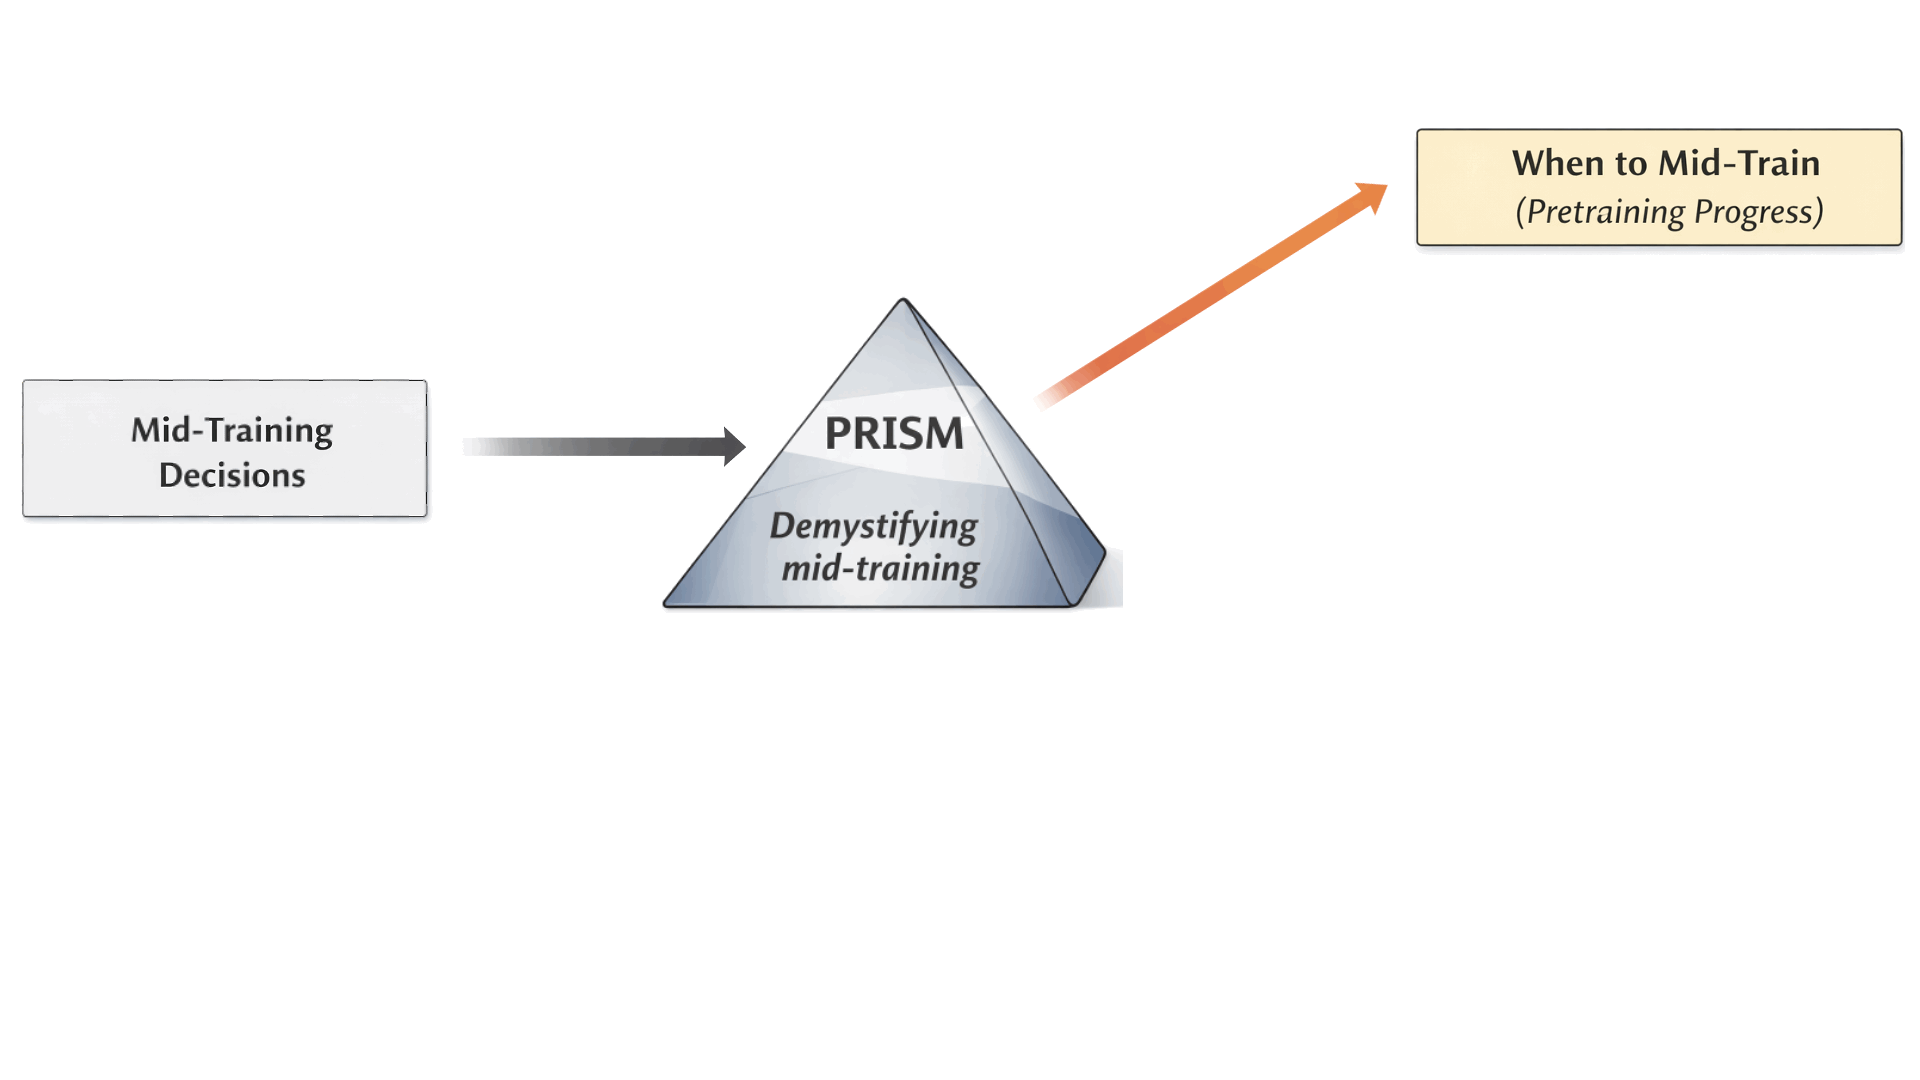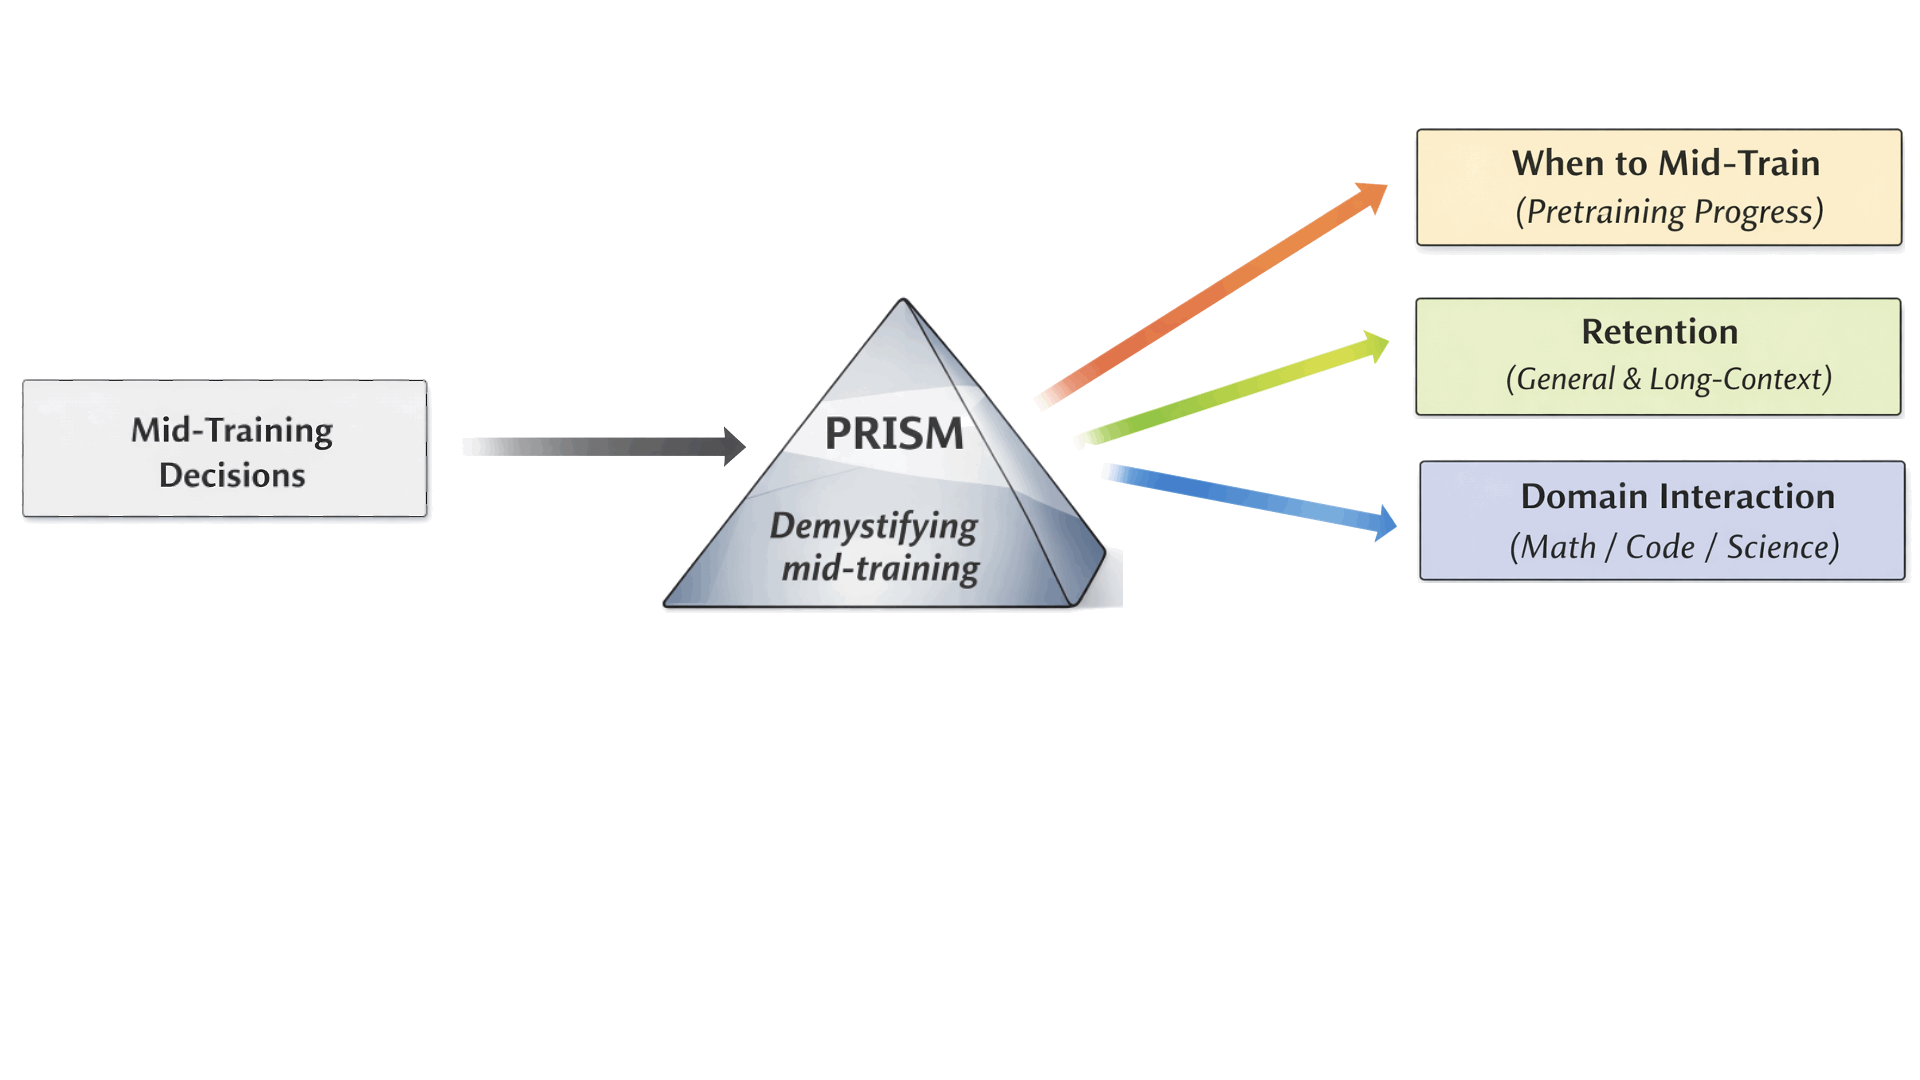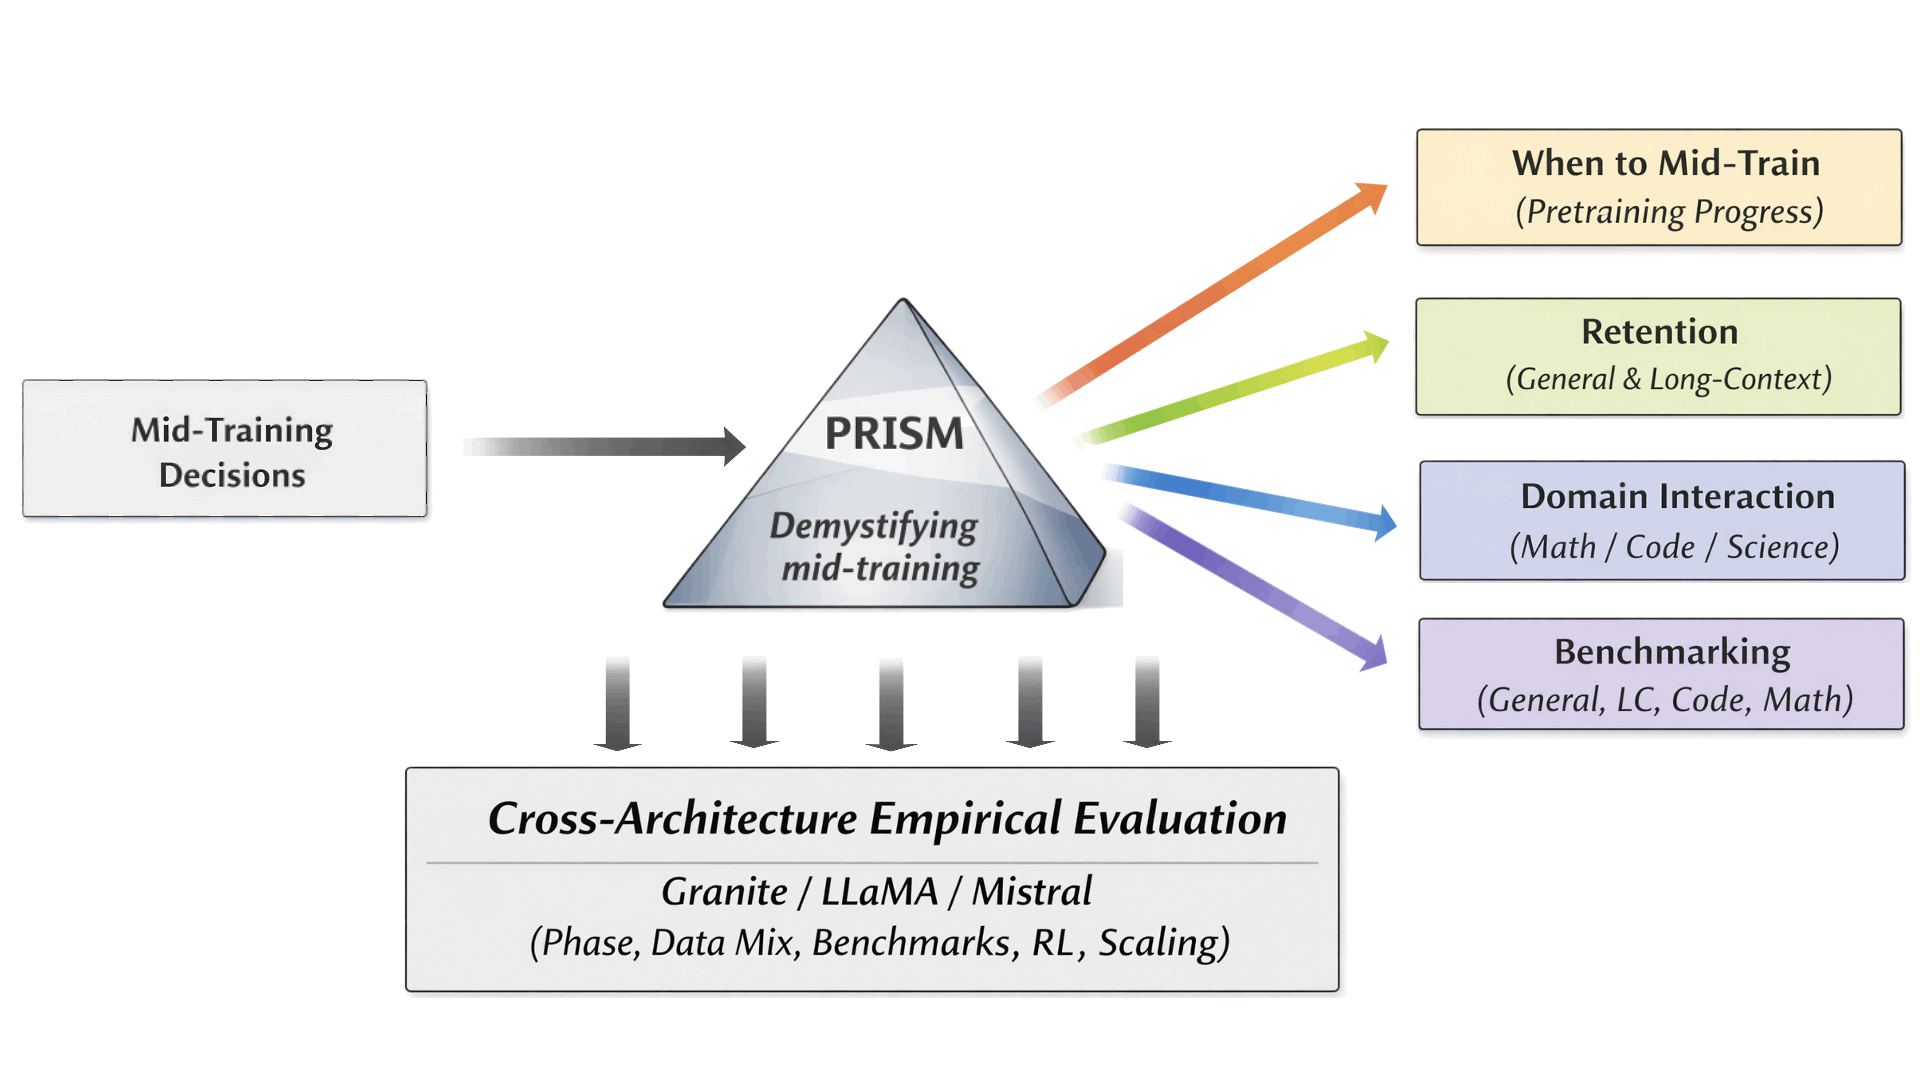 |
PRISM: Demystifying Retention and
Interaction in Mid-Training
Bharat Runwal,
Ashish Agrawal,
Anurag Roy,
Rameswar Panda,
Accepted as a Spotlight Paper (Top 2.2%) at ICML 2026
Project Page |
Paper |
X Thread

A comprehensive empirical study of mid-training design choices for LLMs across 4 model families, 2 architecture types, 7 models, and scales from 3B to 24B parameters.
|
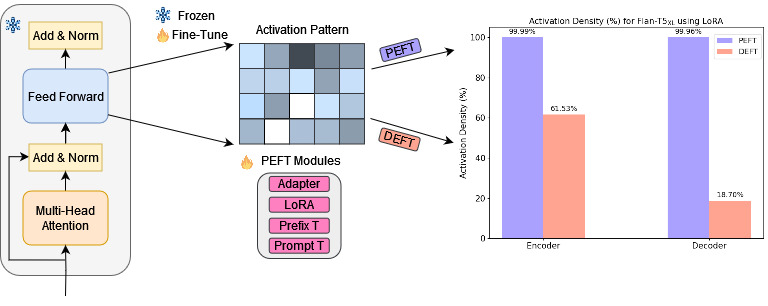 |
From PEFT to DEFT: Parameter Efficient Finetuning for Reducing Activation Density in Transformers
Bharat Runwal,
Tejaswini Pedapati (IBM),
Pin Yu Chen (IBM)
AAAI Main 2025
|
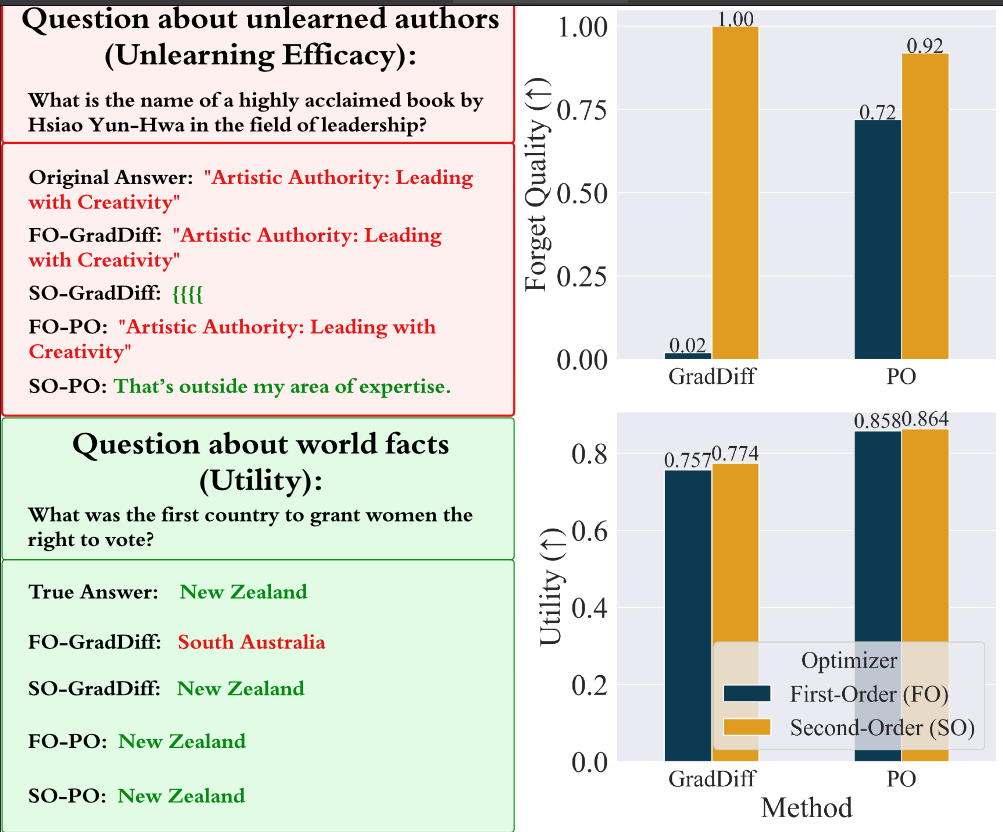 |
SOUL: Unlocking the Power of Second-Order Optimization for
LLM Unlearning
Jinghan Jia, Yihua Zhang, Yimeng Zhang, Jiancheng Liu, Bharat Runwal, James Diffenderfer, Bhavya Kailkhura, Sijia Liu
EMNLP Main Conference, 2024
|
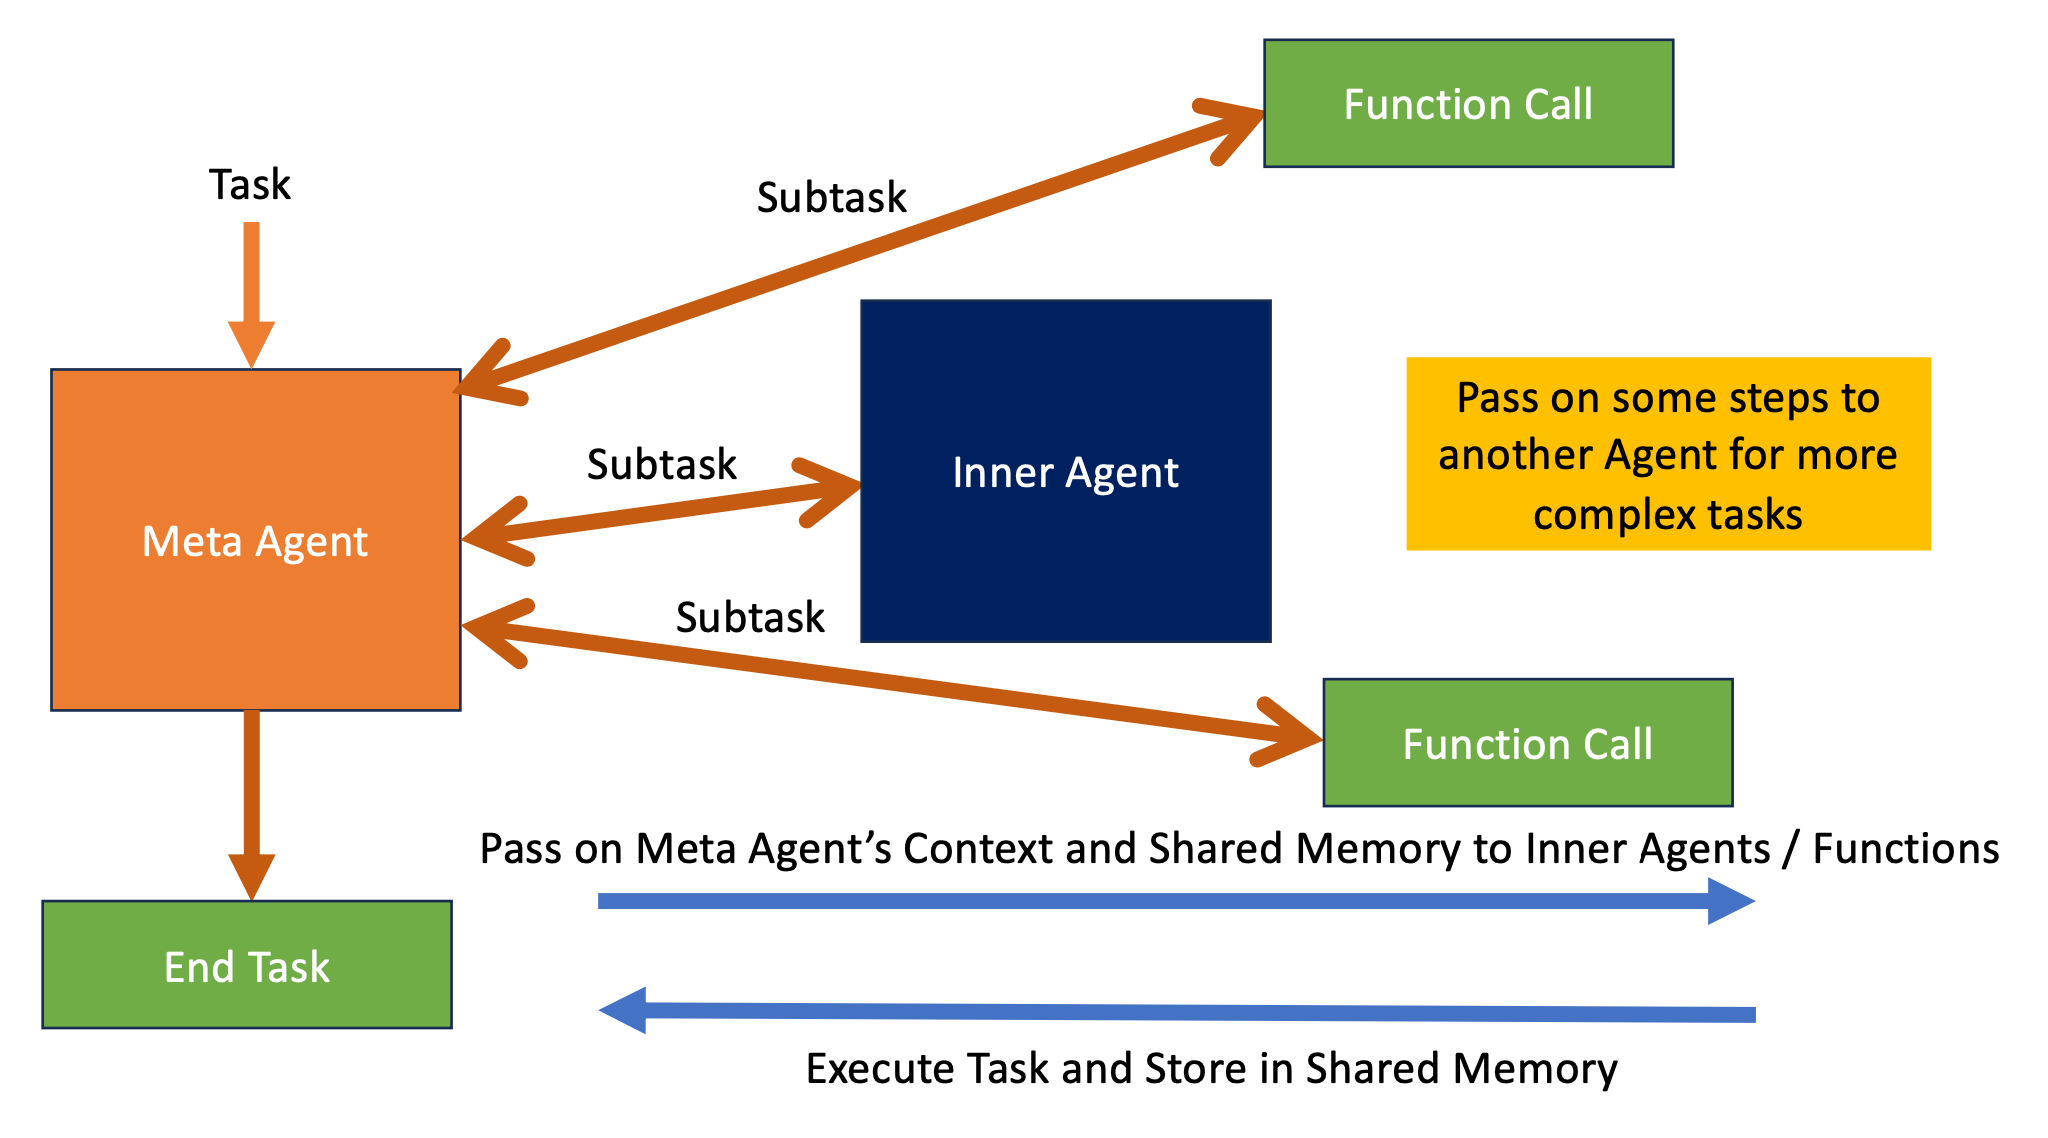 |
TaskGen: A Task-Based, Memory-Infused Agentic Framework using StrictJSON
John Chong Min Tan, Prince Saroj, Bharat Runwal, Hardik Maheshwari, Brian Lim Yi Sheng, Richard Cottrill, Alankrit Chona, Ambuj Kumar, Mehul Motani
|
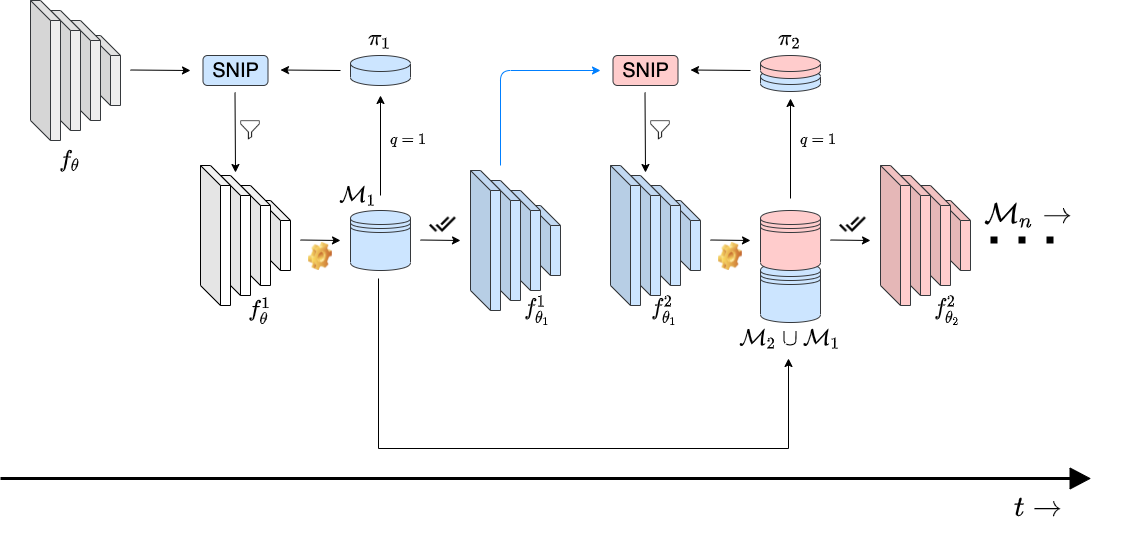 |
APP: Anytime Progressive Pruning
Diganta Misra*,
Bharat Runwal*,
Tianlong Chen,
Zhangyang Wang,
Irina Rish
DyNN workshop at ICML,2022
SNN, 2022
CLL workshop at ACML, 2022
SlowDNN workshop, 2023
project /
paper /
webpage /
abstract /
bibtex
With the latest advances in deep learning, there has been a lot of focus on the online learning paradigm due to its relevance in practical settings. Although many methods have been investigated for optimal learning settings in scenarios where the data stream is continuous over time, sparse networks training in such settings have often been overlooked. In this paper, we explore the problem of training a neural network with a target sparsity in a particular case of online learning: the anytime learning at macroscale paradigm (ALMA). We propose a novel way of progressive pruning, referred to as \textit{Anytime Progressive Pruning} (APP); the proposed approach significantly outperforms the baseline dense and Anytime OSP models across multiple architectures and datasets under short, moderate, and long-sequence training. Our method, for example, shows an improvement in accuracy of $\approx 7\%$ and a reduction in the generalization gap by $\approx 22\%$, while being $\approx 1/3$ rd the size of the dense baseline model in few-shot restricted imagenet training. We further observe interesting nonmonotonic transitions in the generalization gap in the high number of megabatches-based ALMA. The code and experiment dashboards can be accessed at \url{https://github.com/landskape-ai/Progressive-Pruning} and \url{https://wandb.ai/landskape/APP}, respectively.
@misc{misra2022app,
title={APP: Anytime Progressive Pruning},
author={Diganta Misra and Bharat Runwal and Tianlong Chen and Zhangyang Wang and Irina Rish},
year={2022},
eprint={2204.01640},
archivePrefix={arXiv},
primaryClass={cs.LG}
}


|
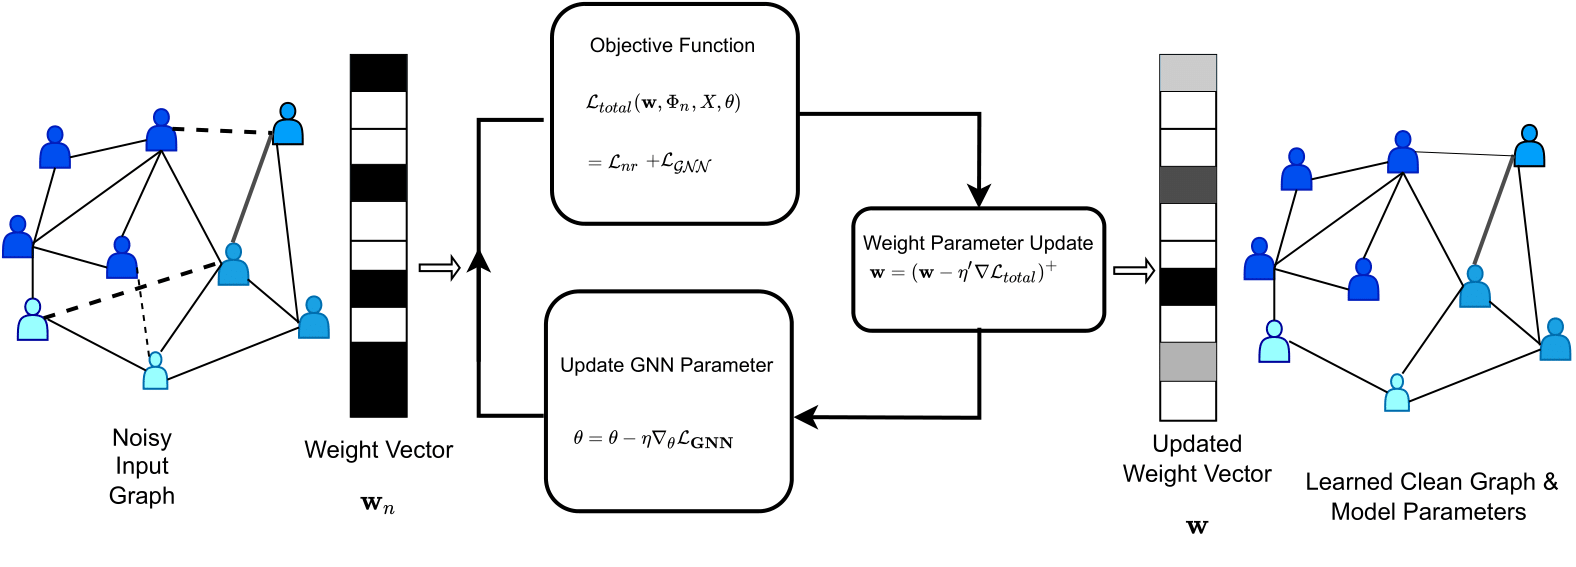 |
Robustifying GNN Via Weighted Laplacian (Best Student Paper Award)
Bharat Runwal,
Vivek Dahiya,
Sandeep Kumar
SPCOM, 2022

|
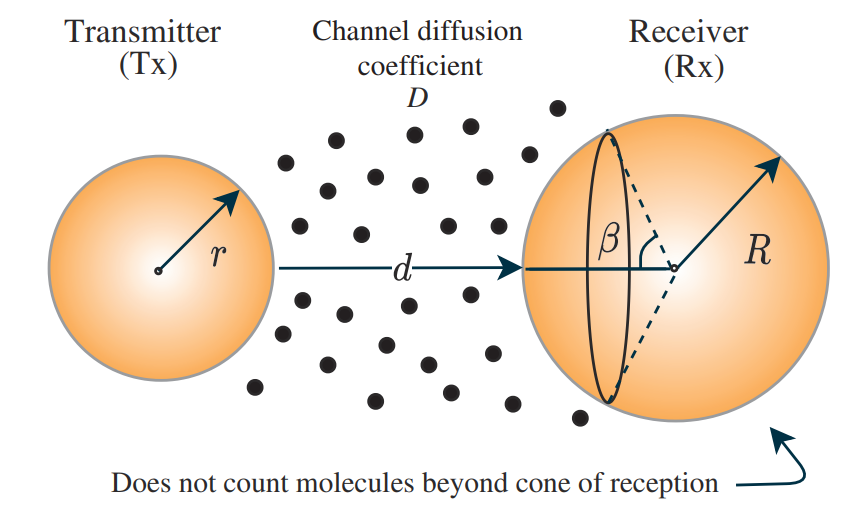 |
Received signal modeling and BER analysis for molecular SISO communications
Arunava Das, Bharat Runwal, O. Tansel Baydas, Dr Oktay Cetinkaya , Prof. Özgür B. Akan
ACM NanoCom 2022
|
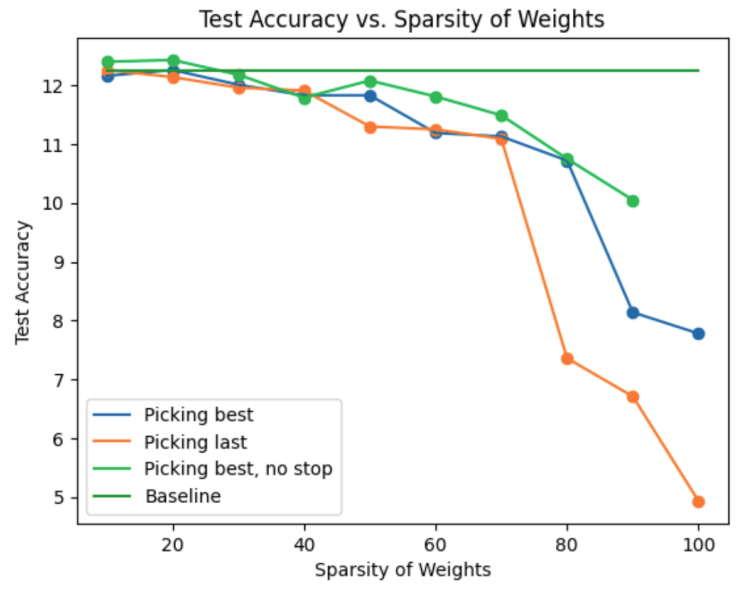 |
Pruning CodeBERT for Improved Code-to-Text Efficiency
Alex Gu, Ria Sonecha, Saaketh Vedantam, Bharat Runwal, Diganta Misra
Sparsity in Neural Networks(SNN) workshop, ICLR 2023
|
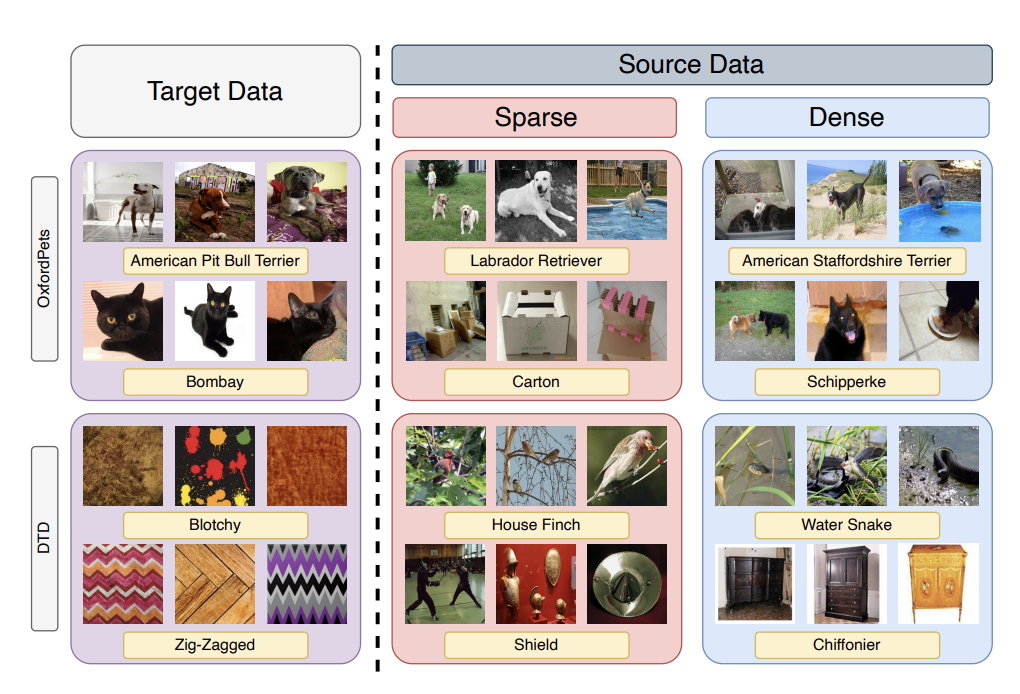 |
Uncovering the Hidden Cost of Model Compression
Diganta Misra* ,
Muawiz Chaudhary,
Agam Goyal*,
Bharat Runwal*,
Pin Yu Chen
PiV @ CVPR, 2024
|
|


